
@reasoning-router/opencode
Adaptive per-step reasoning effort for OpenCode V2
3
+2 in 30 days
1,483
219 in 7 days
47.7
Multi-signal model
6 days ago
2026-10-14
Install and configure
opencode.jsonWrites to this project's opencode.json — applies to this repository only.
opencode.json
{
  "$schema": "https://opencode.ai/config.json",
  "plugin": ["@reasoning-router/opencode@0.1.9"]
}
Writes to ~/.config/opencode/opencode.json — applies to every project.
~/.config/opencode/opencode.json
{
  "$schema": "https://opencode.ai/config.json",
  "plugin": ["@reasoning-router/opencode@0.1.9"]
}
If you want to modify the plugin locally, install it into the project and reference the local path.
shell
pnpm add -D @reasoning-router/opencodeOpenCode loads npm dependencies through its embedded runtime on startup and caches them locally — no manual global install needed.


Keep the quality. Spend less reasoning. reasoning-router asks a
classifier how much reasoning each step of a coding session needs, so one
strong model handles quick edits and hard debugging without you switching
effort levels by hand. It works in OpenCode, Pi, Codex CLI, and any client
that can talk to a local proxy, with the classifier you choose.
In our SWE-bench Verified runs on GPT-6 Astra, Jev-routed effort solved every
task that fixed high effort solved, and how much it saved depended on how
hard the task was. On a short Flask fix, Jev used 52% fewer output tokens
(including reasoning) and finished in about half the time. On harder Django and
pytest issues, output fell by only 5–7% and time changed by less than 10%.
These are a few selected tasks, so treat them as examples, not an expected
saving. See the evaluation.
Status: alpha. Install the packages below from npm as described in each package README.
Quick start
Pick your harness. Each example uses Jev with a TypeSafe key; see Classifiers for the others.
OpenCode — add the plugin to opencode.json
(full guide):
{
  "plugins": [{ "package": "@reasoning-router/opencode", "options": {
    "classifier": { "provider": "jev", "apiKey": "{env:REASONING_ROUTER_CLASSIFIER_API_KEY}" },
    "wrap": { "openai": ["openai/gpt-6-astra"] }
  }}],
  "model": "reasoning-router/gpt-6-astra"
}
Pi — Claude models only (full guide):
export REASONING_ROUTER_CLASSIFIER_API_KEY=<typesafe-key>
pi install npm:@reasoning-router/pi
pi --model reasoning-router/claude-opus-5-5
Codex CLI or any Responses/Messages client — run the local proxy and point
the client at http://127.0.0.1:4320/v1 (full guide):
REASONING_ROUTER_CLASSIFIER_API_KEY=<typesafe-key> \
REASONING_ROUTER_UPSTREAM_BASE_URL=https://api.openai.com/v1 \
REASONING_ROUTER_UPSTREAM_AUTH=bearer \
REASONING_ROUTER_UPSTREAM_API_KEY=<openai-key> \
npx @reasoning-router/proxy
For Codex, add a profile at ~/.codex/reasoning-router.config.toml that keeps the
model and swaps only the provider, then run codex -p reasoning-router (Codex 0.161.0
or later), adding -m gpt-6-sol or another model to override the default. Plain codex is unchanged. The classifier picks the effort, so
Codex's own effort setting is ignored. To use a ChatGPT subscription instead
of an API key, chain the proxy to CLIProxyAPI
(guide):
model = "gpt-6-astra"
model_provider = "reasoning-router"

[model_providers.reasoning-router]
name = "reasoning-router"
base_url = "http://127.0.0.1:4320/v1"
wire_api = "responses"
If the classifier is slow or unavailable, the request still runs, at the
fallback effort (high by default).
How it works
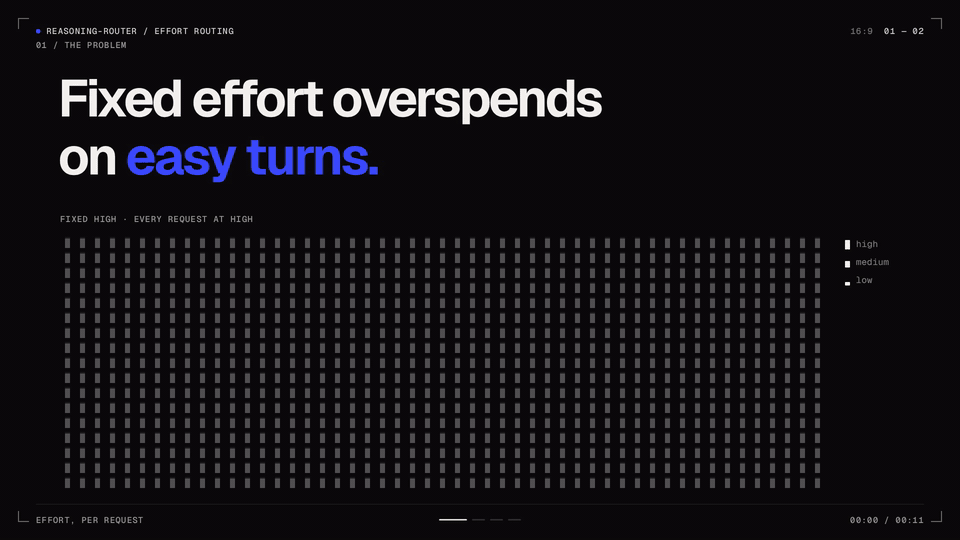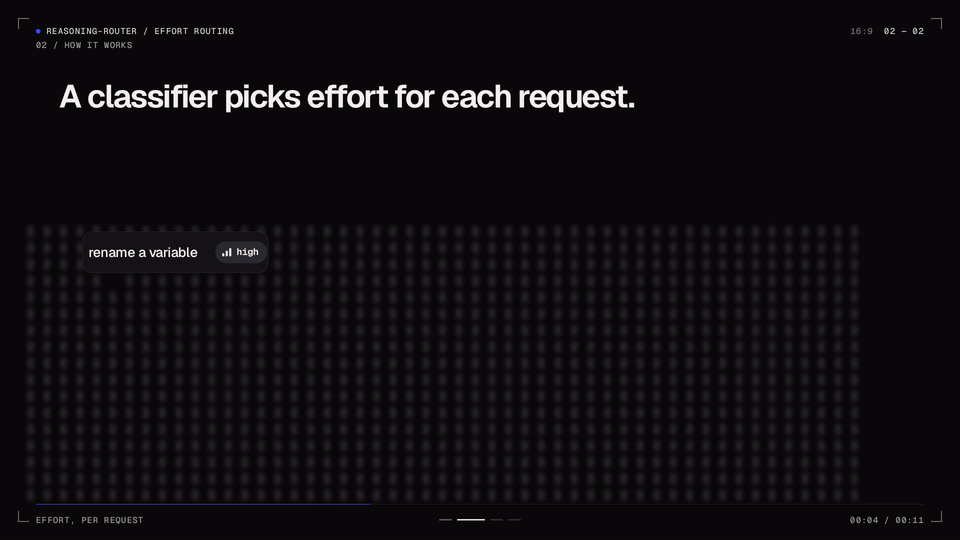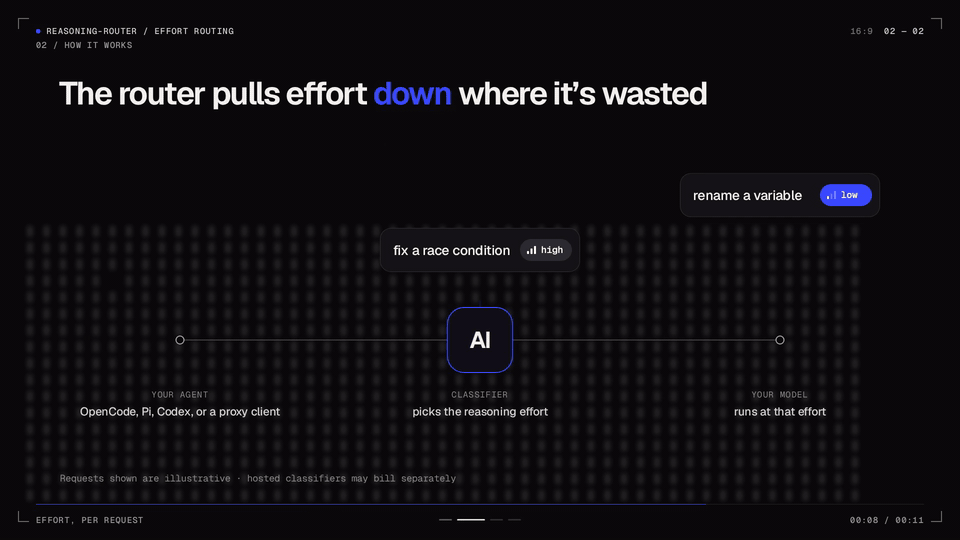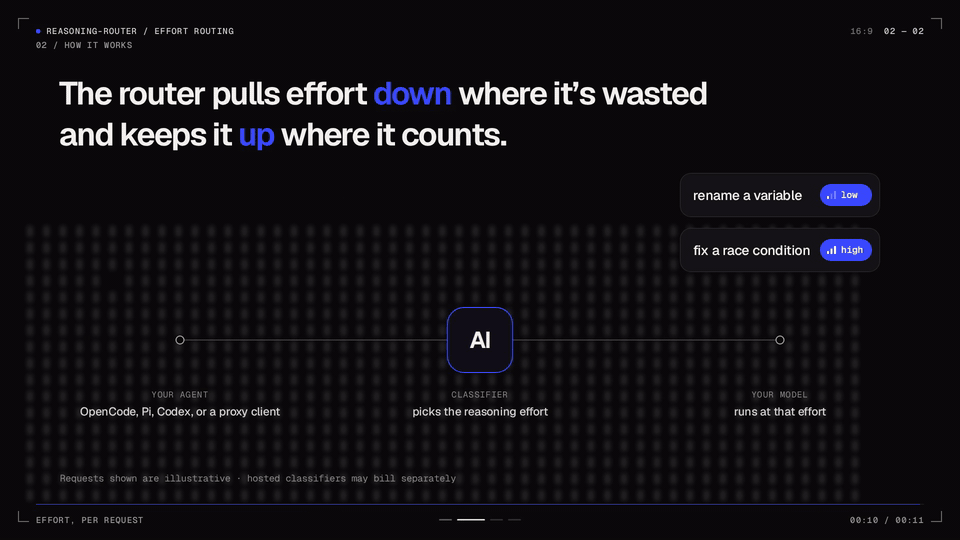
For each primary request, the router:
- Sends a bounded summary of the recent conversation to the classifier, which
picks a reasoning effort (for example
lowfor a rename,highfor a failing test). - Adds that effort to the request as an OpenAI
configuration_updateitem or an Anthropic effort-only system message. Earlier updates stay in place, so the prompt prefix stays cacheable. - Sends the request to your model endpoint and streams the response back unchanged.
What is sent where
- To the classifier: bounded excerpts of recent user and assistant text, up to 8 recent tool results (with tool names and error flags), a short failure summary, and the model ID. Hosted-tool and computer-use payloads are not sent. Laya, Kev, CLM, and SGLang run on your own server.
- To your endpoint: the full request, with the effort update added.
- Logged: metadata only (IDs, model, effort, latency, token counts), and only to the proxy's stdout or a decision log you enable. Prompts, tool output, credentials, and raw errors are never logged.
See docs/behavior.md for the details.
Why
A single model at low effort and at max effort can differ as much as separate model tiers do, in both capability and price.
You could route easy steps of a coding session to a cheaper model, but switching models invalidates the prompt cache. On a long session, rebuilding that context can cost more than the cheaper model saves.
Models that let you change reasoning effort mid-conversation keep the cache,
so a session can stay on one strong model. It can use low effort for simple
edits and tool calls and save high or max for architecture and hard debugging.
reasoning-router picks the effort for each step.
Alpha limitations
- Tested with: Node.js 24.x, OpenCode V2 2.0.18, Pi 1.0.4, and Codex CLI 0.159.0 and 0.161.0 (through the proxy). Other versions may work but are untested.
- Models: only those listed under Supported models. Other models are rejected locally. Pi routes Claude models only.
- Classifiers: the router asks the configured classifier and applies its answer; it makes no claim about how well any classifier picks effort for your workload.
- Proxy: for trusted local use only; see its trust model.
Report vulnerabilities as described in SECURITY.md.
Intent
reasoning-router asks a classifier how much reasoning each step of an agent
session needs, then applies that effort to the outgoing model request without
breaking the prompt cache.
- Any classifier. Jev is one of several decision
models that can classify how much reasoning a step needs, and more are being
released. Which classifier to use is configuration, not a dependency:
reasoning-routermust not depend on Jev or any single provider. - Any harness. The same routing runs inside OpenCode, Pi, or any client that can talk to the standalone proxy.
The packages are:
@reasoning-router/core: the shared, harness- and classifier-independent router.@reasoning-router/opencode: the OpenCode V2 plugin.@reasoning-router/classifiers: the classifiers (Jev, Cloudflare Clef, Laya, Kev, OpenAI Decisions, CLM, Microsoft-Decision-1, Liquid d1, and SGLang), selected byclassifier.provider.@reasoning-router/pi: the Pi extension (Claude models only, for now).@reasoning-router/proxy: the standalone Responses/Messages proxy (commandreasoning-router).
See docs/architecture.md for the problem statement, the package plan, and the open questions, and docs/behavior.md for the router's wire behavior.
Classifiers
Pick a classifier with REASONING_ROUTER_CLASSIFIER (proxy and Pi) or the
plugin's classifier.provider option (OpenCode). The examples below use the
proxy; the OpenCode plugin takes the same settings as classifier.apiKey,
classifier.baseUrl, classifier.accountId, and classifier.model, and
falls back to these environment variables. See
docs/environment.md and
@reasoning-router/classifiers for every setting.
Jev (default)
Jev is a hosted decision model from TypeSafe. Get a TypeSafe API key, then:
REASONING_ROUTER_CLASSIFIER=jev \
REASONING_ROUTER_CLASSIFIER_API_KEY=<typesafe-key> \
reasoning-router
To use a Vercel AI Gateway key instead, also set
REASONING_ROUTER_CLASSIFIER_BASE_URL=https://ai-gateway.vercel.sh/typesafe.
Cloudflare Clef
Clef runs on Cloudflare Workers AI. Create a Cloudflare API token with Workers AI permissions, then:
REASONING_ROUTER_CLASSIFIER=clef \
REASONING_ROUTER_CLASSIFIER_API_KEY=<cloudflare-token> \
REASONING_ROUTER_CLASSIFIER_ACCOUNT_ID=<cloudflare-account-id> \
REASONING_ROUTER_CLASSIFIER_MODEL=clef \
reasoning-router
Set REASONING_ROUTER_CLASSIFIER_MODEL to clef, clef-omni, or
clef-flash. It is required.
Laya
Laya is an open-source,
Jev-compatible decision model that you run yourself. The router only calls
it over HTTP; it never installs or loads the model. Start Laya's
laya-serve, then point the router at it:
pip install "laya[serve]"
LAYA_HOST=127.0.0.1 LAYA_PRELOAD=1 laya-serve   # http://127.0.0.1:8000
REASONING_ROUTER_CLASSIFIER=laya reasoning-router
The default base URL is http://127.0.0.1:8000. A remote server must use
HTTPS. Set REASONING_ROUTER_CLASSIFIER_API_KEY only if the server sets
LAYA_API_KEY, and set REASONING_ROUTER_CLASSIFIER_MODEL to choose a
checkpoint (english, multilingual, or typed-decisions).
Kev
Kev is an open-source, Jev-compatible
family of decision models that you run yourself with its kev.serve. The
router only calls it over HTTP:
uv run --extra serve python -m kev.serve --run jaredpalmer/kev-4b@v1.0   # http://127.0.0.1:8008
REASONING_ROUTER_CLASSIFIER=kev reasoning-router
See docs/proposals/kev.md for the pinned version, the confirmed HTTP contract, auth, limits, and what is not yet verified.
OpenAI Decisions
The openai-decisions classifier calls OpenAI's Decisions API (public beta,
model gpt-6-luna) with your own OpenAI API key:
REASONING_ROUTER_CLASSIFIER=openai-decisions \
REASONING_ROUTER_CLASSIFIER_API_KEY="$OPENAI_API_KEY" \
reasoning-router
It is tested against mocked responses only; live compatibility and effort-selection quality are unverified. See packages/classifiers for the privacy boundary, regional endpoints, and cost.
CLM
CLM is a decision model that you run
yourself with its clm-serve. clm-serve needs a separate pooling backend
(Qwen3-8B embeddings, for example vLLM) that you also run. The router only
calls clm-serve over HTTP:
vllm serve Qwen/Qwen3-8B --served-model-name qwen3-8b --runner pooling --max-model-len 2048 --host 127.0.0.1 --port 8090
clm-serve --host 127.0.0.1 --no-ui   # http://127.0.0.1:8700
REASONING_ROUTER_CLASSIFIER=clm reasoning-router
The default base URL is http://127.0.0.1:8700. Set
REASONING_ROUTER_CLASSIFIER_API_KEY only if the server sets CLM_API_KEY,
and REASONING_ROUTER_CLASSIFIER_MODEL to choose a CLM head (the server
defaults to clm-latest). See docs/classifiers/clm.md
for the pinned version, the pooling backend, and the 2,048-token truncation.
Only API compatibility has been verified. Effort-decision quality has not.
Microsoft-Decision-1
Microsoft-Decision-1 is Microsoft's decision model on Microsoft Foundry. Deploy it in your Foundry resource, then use the resource endpoint, deployment name, and API key from the deployment details page:
REASONING_ROUTER_CLASSIFIER=microsoft-decision \
REASONING_ROUTER_CLASSIFIER_BASE_URL=https://<resource>.services.ai.azure.com \
REASONING_ROUTER_CLASSIFIER_MODEL=<deployment-name> \
REASONING_ROUTER_CLASSIFIER_API_KEY=<foundry-api-key> \
reasoning-router
All three settings are required. Only API keys are supported, not Microsoft Entra ID tokens. It is tested against mocked responses only; live compatibility and effort-selection quality are unverified. See packages/classifiers for details.
Liquid d1
Liquid d1 is Liquid AI's hosted decision model. Create a key at console.liquid.ai, then:
REASONING_ROUTER_CLASSIFIER=liquid \
REASONING_ROUTER_CLASSIFIER_API_KEY=<liquid-key> \
reasoning-router
To use a Vercel AI Gateway key instead, also set
REASONING_ROUTER_CLASSIFIER_BASE_URL=https://ai-gateway.vercel.sh/typesafe.
Set REASONING_ROUTER_CLASSIFIER_MODEL=d1:free for Liquid's free text-only
model. It is tested against mocked responses only; live compatibility and
effort-selection quality are unverified. See
packages/classifiers
for details.
SGLang
SGLang serves a System One endpoint for chat models (v0.5.21 and later) and for decision checkpoints such as PPLX-Decider (nightly builds). You run the server yourself; the router only calls it over HTTP:
python -m sglang.launch_server --model-path Qwen/Qwen3.8-27B --host 127.0.0.1 --port 30000
REASONING_ROUTER_CLASSIFIER=sglang reasoning-router
The default base URL is http://127.0.0.1:30000. Set
REASONING_ROUTER_CLASSIFIER_API_KEY only if the server runs with
--api-key. See docs/classifiers/sglang.md for
the pinned version, model and template restrictions, and the difference
between a chat model's next-token scores and a calibrated decision
checkpoint. Only API compatibility has been verified. Effort-decision quality
has not.
Supported models
The router rejects any other model locally. Whether your upstream account can use a model is a separate question.
| Model | ID | API | Efforts | Base effort | Pi |
|---|---|---|---|---|---|
| GPT-6 Astra | gpt-6-astra |
Responses | low–max | medium | No |
| GPT-6 Luna | gpt-6-luna |
Responses | none–max | medium | No |
| GPT-6 Sol | gpt-6-sol |
Responses | none–max | medium | No |
| GPT-6.1 Sol | gpt-6.1-sol |
Responses | low–max | medium | No |
| Claude Fable 5.1 | claude-fable-5-1 |
Messages | low–max | high | Yes |
| Claude Mythos 5.1 | claude-mythos-5-1 |
Messages | low–max | high | No (Pi 1.0.4) |
| Claude Opus 5.5 | claude-opus-5-5 |
Messages | low–max | medium | Yes |
| Claude Opus 5 | claude-opus-5 |
Messages | low–max | high | Yes |
| Claude Sonnet 5.5 | claude-sonnet-5-5 |
Messages | low–max | medium | Yes |
Efforts run in the order none, low, medium, high, xhigh, max. Base effort is
the model's default request-level effort, which REASONING_ROUTER_BASE_EFFORT
overrides. When classification fails, the router uses the fallback effort,
high by default for every model; set it with
REASONING_ROUTER_FALLBACK_EFFORT or the plugin's fallbackEffort option.
See docs/behavior.md and
docs/classification-policy.md. The registry
lives in
packages/core/src/models.ts.
Development
Requires Node.js 24.x.
npm ci
npm run check   # typecheck + lint + test
See AGENTS.md for the full command list and repo conventions.
Reversible design and tooling decisions are recorded in docs/architecture.md.
License
Similar plugins

Magic Compact
magic-compact
Lossless context compression plugin for OpenCode.

Commandcode
@herouucn/opencode-commandcode
Inject Command Code API provider into opencode — access Claude, GPT, Gemini, DeepSeek, Qwen, Kimi, GLM, MiniMax & Step via unified Command Code API. / 将 Command Code API provider 注入 opencode —— 通过统一的 Command Code API 使用 Claude、GPT、Gemini、DeepSeek、Qwen、Kim

Codex Usage
opencode-plugin-codex-usage
OpenCode TUI plugin that shows live Codex usage limits in the session sidebar.